
I am a postdoctoral researcher in the Department of Computer Science at The University of Hong Kong, working with Prof. Hengshuang Zhao. I received my Ph.D. from the School of Electronic Information and Communications at Huazhong University of Science and Technology, supervised by Prof. Xiang Bai.
I have eight years of experience in autonomous driving and two years in embodied AI. My current research focuses on Physical AI and embodied foundation models, spanning vision-language-action (VLA) models, world models, embodied reasoning, and efficient inference for real-world deployment.
Multimodal foundation models, robotic learning, and cross-embodiment generalization.
Vision-language-action models, reasoning-to-action, streaming policies, and task execution.
Action-conditioned prediction, physics-aware modeling, simulation, and policy learning.
Real-time execution, adaptive test-time computation, and action verification.
Job Market: I am open to private conversations about research and technical leadership opportunities in embodied AI and multimodal foundation models, particularly those involving research direction, core team building, and real-world deployment.
I am also interested in faculty positions at universities, where I can build an independent research group in Physical AI, mentor students, and contribute to teaching in AI and robotics. Please feel free to reach out at happinesslzcq@gmail.com.
Research Vision
My long-term goal is to build general-purpose embodied intelligence systems that integrate data, models, simulation, evaluation, and deployment. The current blueprint is organized around embodied data engines, embodied foundation models, 4D world models and simulation, efficient streaming inference, and an intelligent robotic OS for manipulation, navigation, autonomous driving, and cross-embodiment deployment.

News
- Oct 2026: 🚀 VeriVLA is released, using latent world models for adaptive test-time verification of flow-based VLA actions.
- Oct 2026: 🚀 Atomic-WAM is released, connecting task reasoning to robotic action through execution-grounded atomic-motion descriptions.
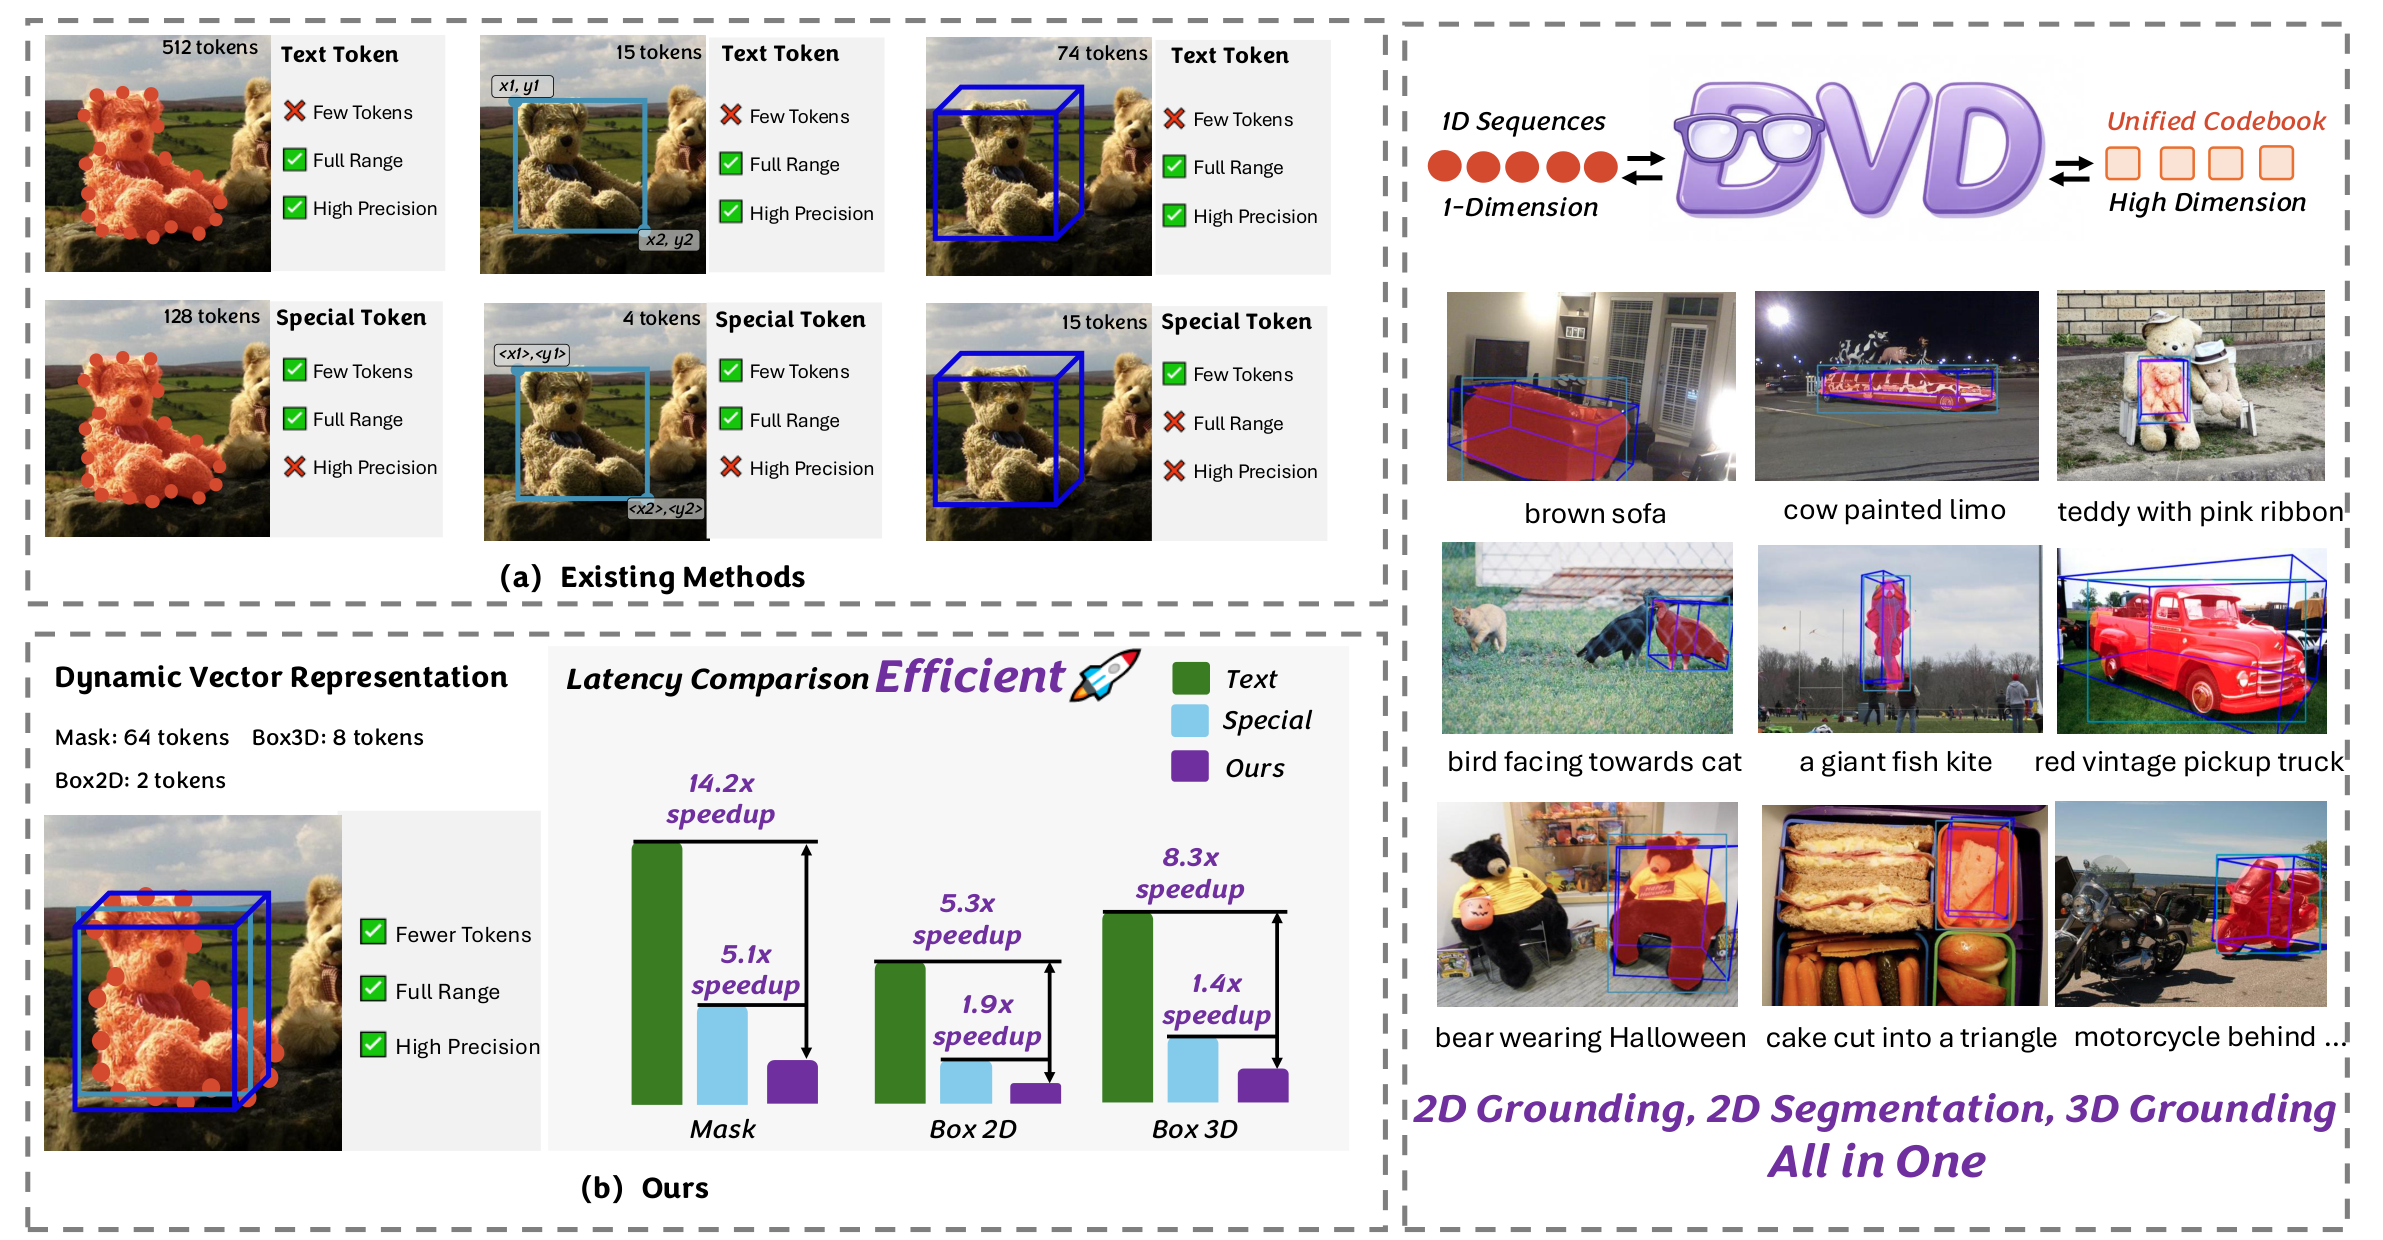
- Oct 2026: 🚀 DVD is released, enabling efficient MLLM-based 2D and 3D perception with dynamic vector decoding.
- Sep 2026: 🚀 PanoVLN is released, exploring effective panoramic vision-and-language navigation.
- Sep 2026: 🎉 Six papers are accepted by NeurIPS 2026: StreamPI, Read It Back / SpectraReward (Spotlight ✨), EO-WM, FlowR2A, FASTER, and SRL-MPC.
- Early Sep 2026: 🎉 Invited to serve as an Area Chair (AC) for ICLR 2027.
- Aug 2026: 🚀 StreamPI and SRL-MPC are released.
- Jul 2026: 🚀 Read It Back / SpectraReward is released.
- Jul 2026: 🚀 ACE-Brain-0.5 is released.
- Jun 2026: 🎉 Visual Spatial Tuning is accepted by ECCV 2026.
- Jun 2026: EO-WM, FlowR2A, Metis, and IR-SIM are released.
- May 2026: 🎉 AlphaGRPO is accepted by ICML 2026.
- May 2026: MCNav and AlphaGRPO are released.
- Mar 2026: FASTER and ACE-Brain-0 are released.
- Feb 2026: 🎉 DrivePI and GenieDrive are accepted by CVPR 2026.
- Dec 2025: DrivePI and GenieDrive are released.
- Nov 2025: UniLION and Visual Spatial Tuning are released.
- Nov 2025: Invited to give a talk at Huawei Yinwang Intelligent Technology, with over 100 researchers attending.
- Sep 2024: 🎉 LION is accepted by NeurIPS 2024.
- Jul 2024: 🎉 SEED and OPEN are accepted by ECCV 2024.
- Sep 2023: 🎉 QTNet is accepted by NeurIPS 2023.
- Nov 2022: 🎉 StereoDistill is accepted by AAAI 2023 and EPNet++ is accepted by TPAMI.
- Nov 2019: 🎉 TANet is accepted by AAAI 2020 as an oral presentation.
Publications
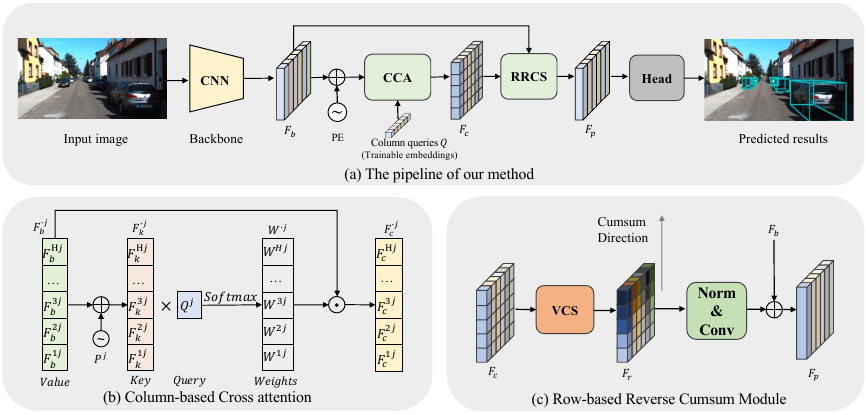
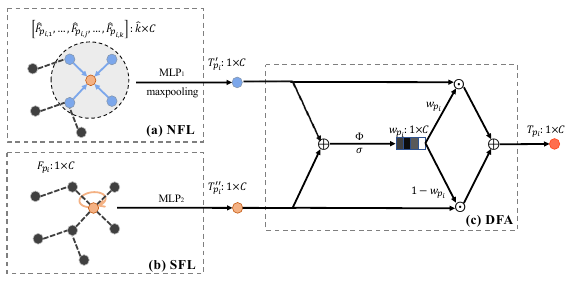
I have published 40+ papers in venues including TPAMI, TIP, CVPR, ICCV, ECCV, NeurIPS, ICML, AAAI, IROS, TITS, and ICRA. Google Scholar reports 2,603 citations, an h-index of 18, and an i10-index of 22.
Selected publications and recent arXiv preprints are listed below. Full publication list on Google Scholar.
*: Equal contribution, ✉: Corresponding Author, †: Project Leader, ‡: Equal advising.
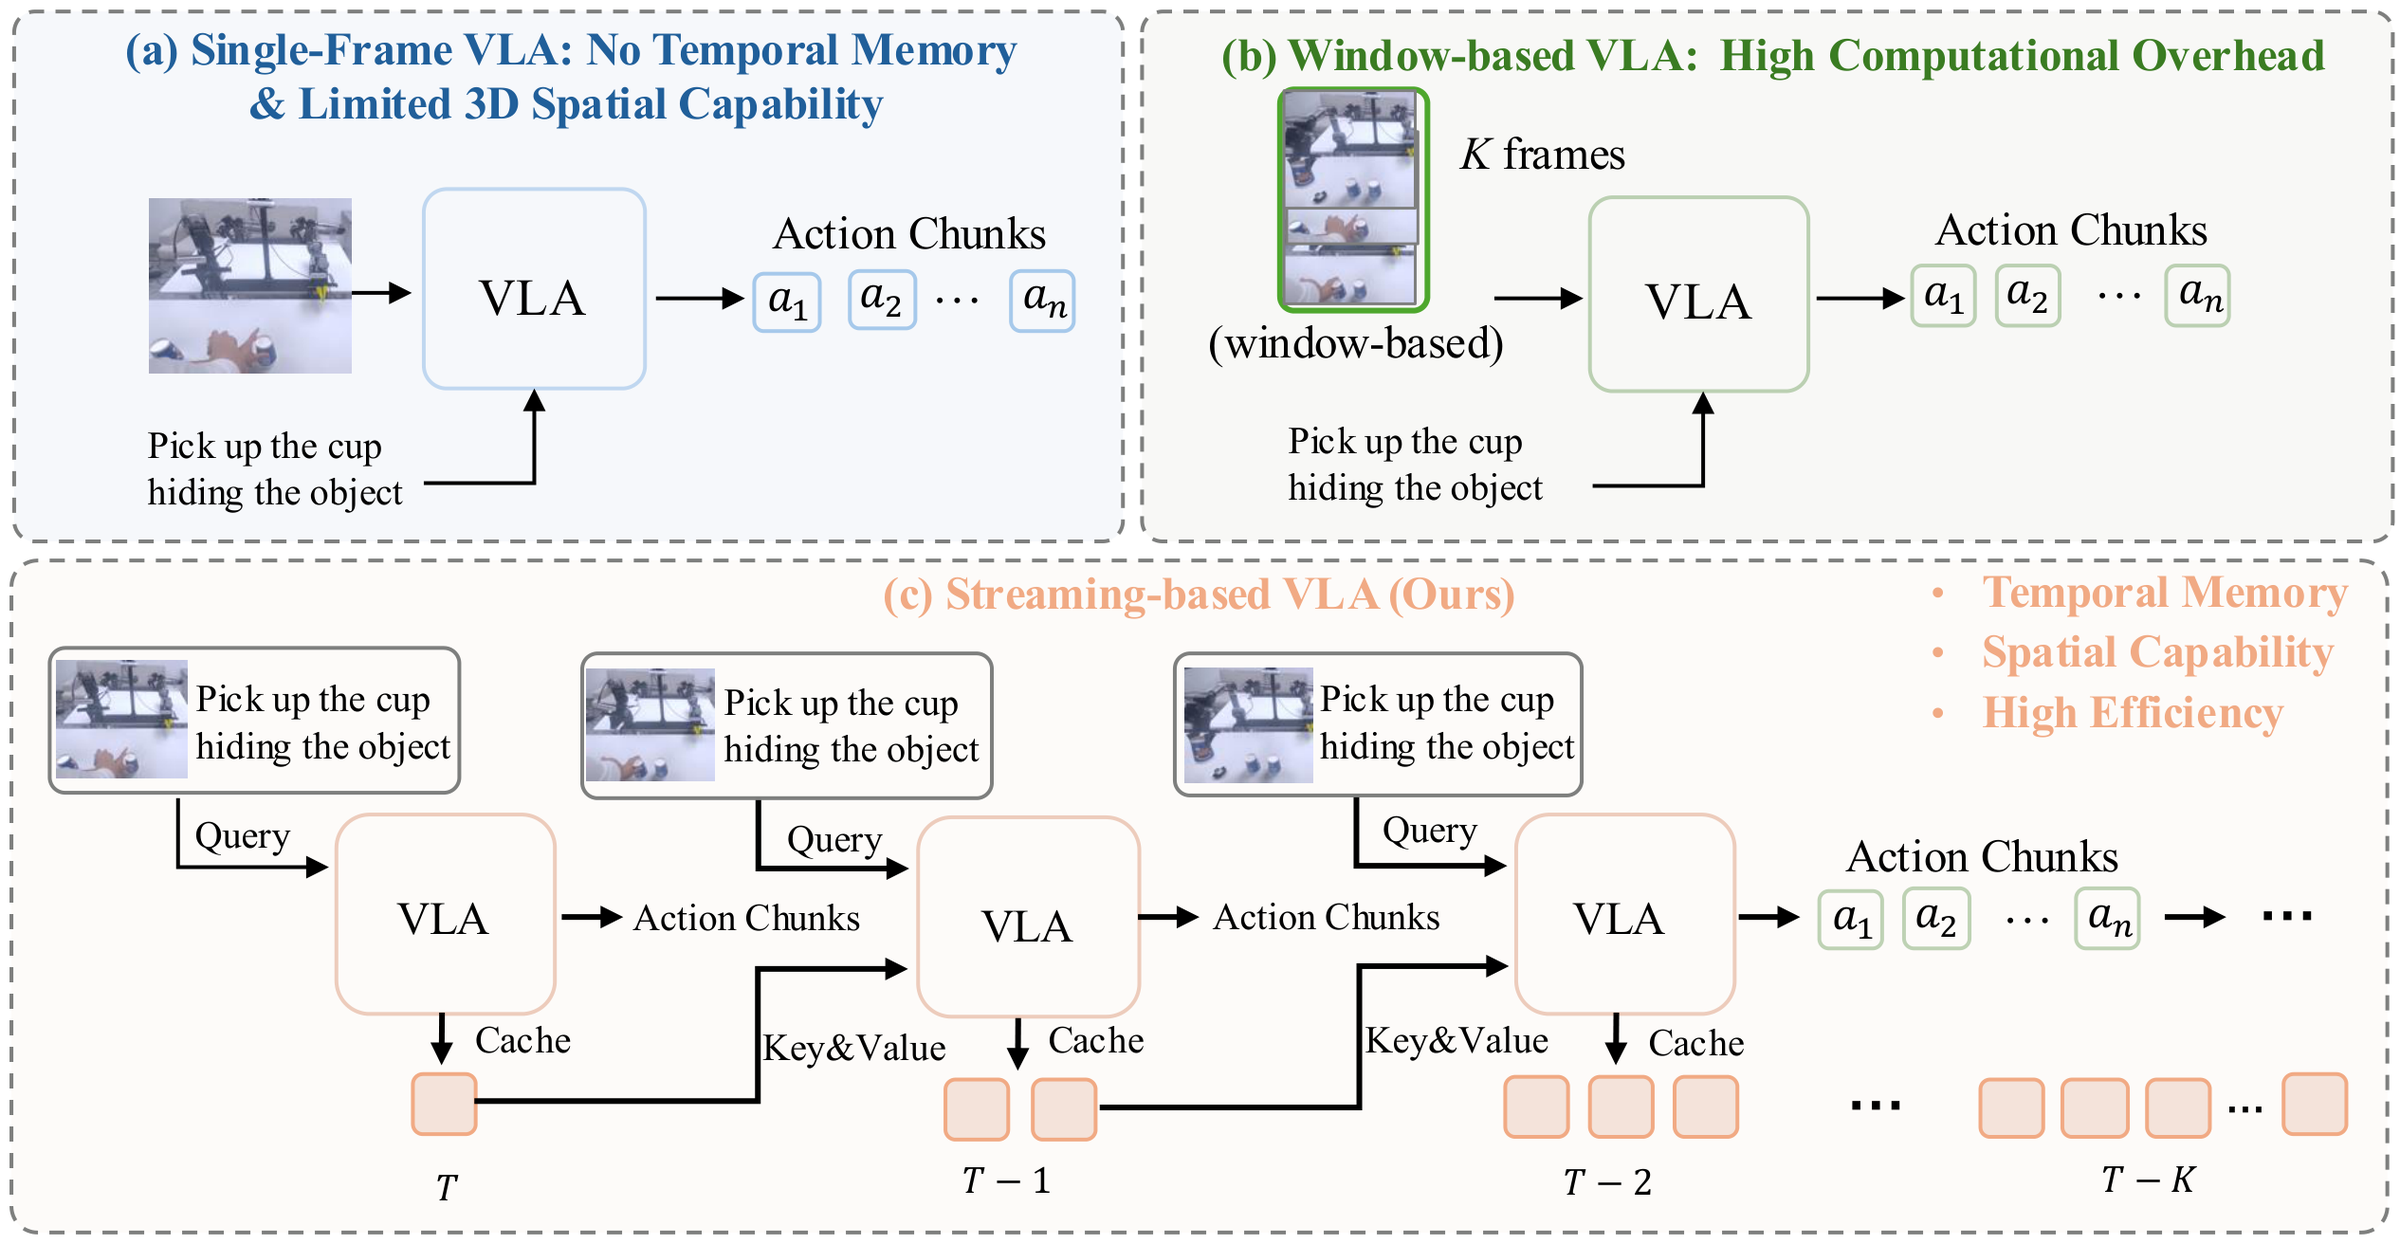
Embodied Foundation Models & VLA 6 papers
General-purpose embodied intelligence through VLA policies, cross-embodiment learning, and multimodal foundation model training and alignment.


World Models & World-Action Models 4 papers
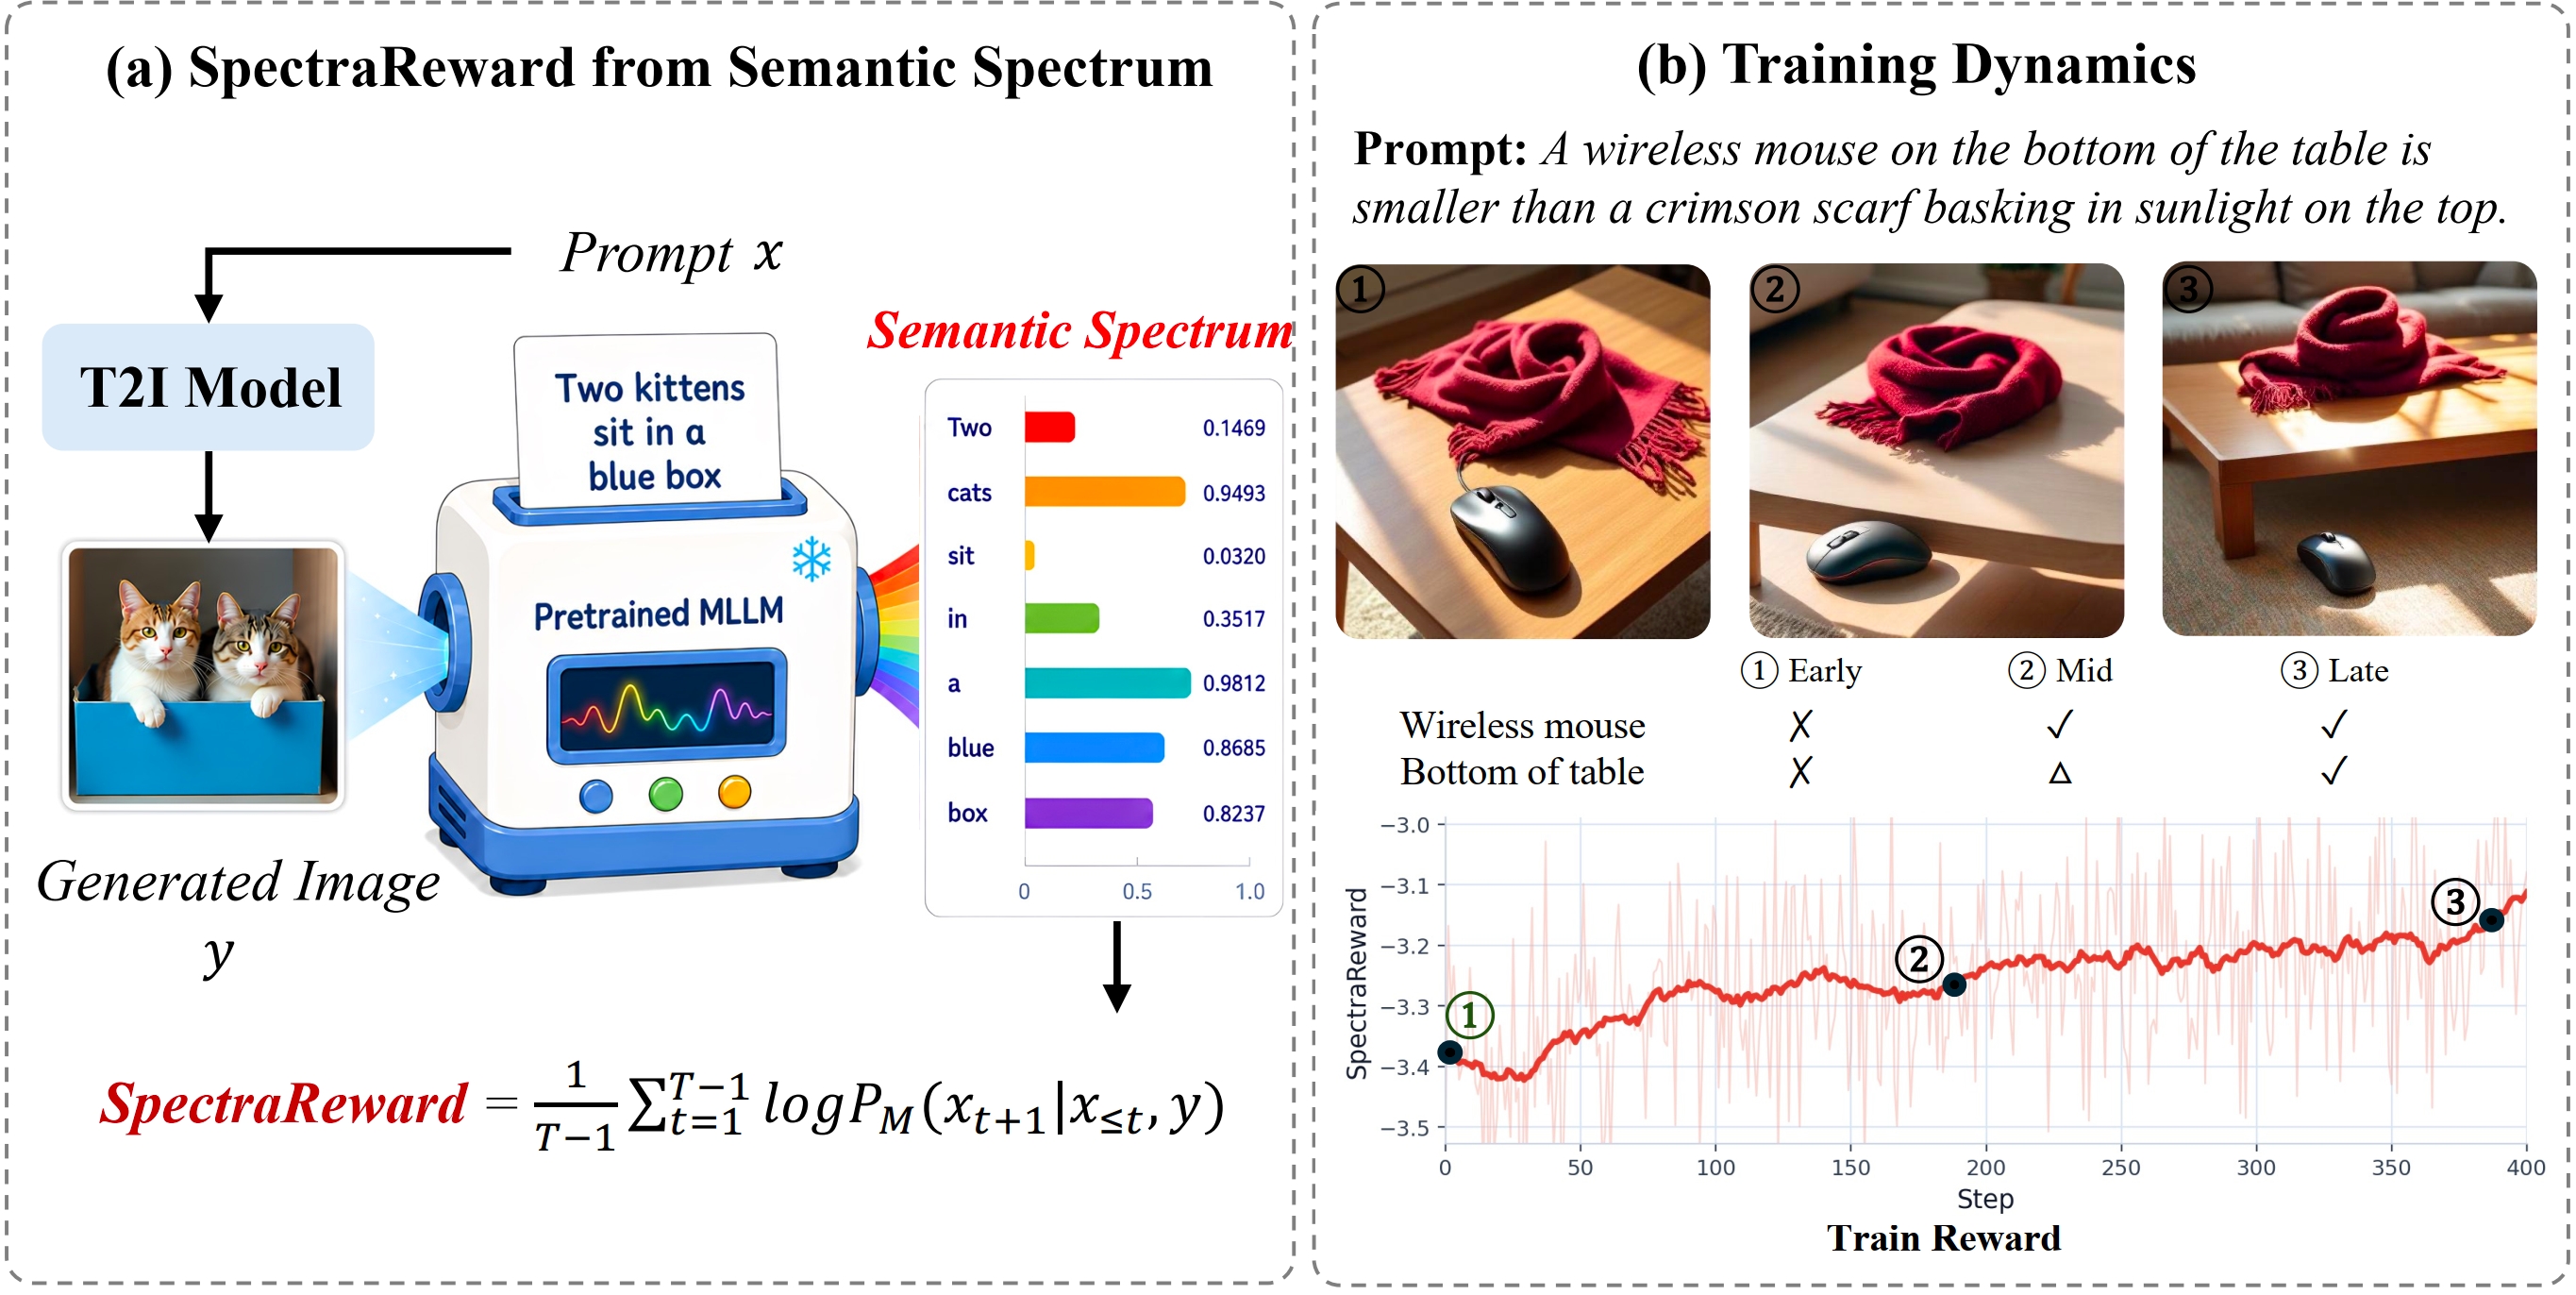
Action-conditioned world modeling, joint world-action prediction, and physics-aware simulation.


Embodied Reasoning & Planning 6 papers
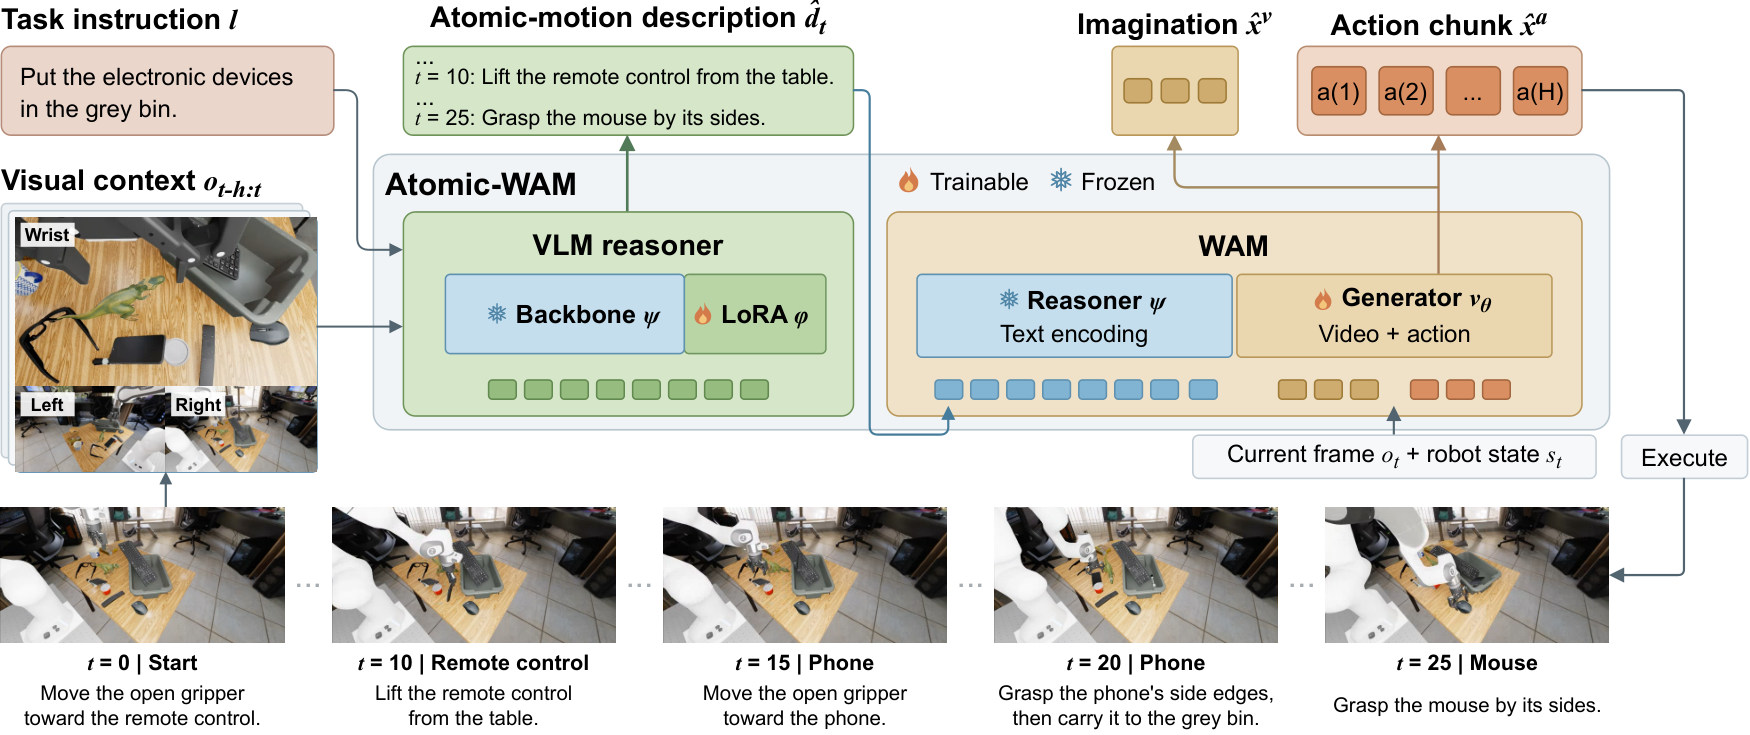
Connecting multimodal understanding and memory to navigation, planning, and control.

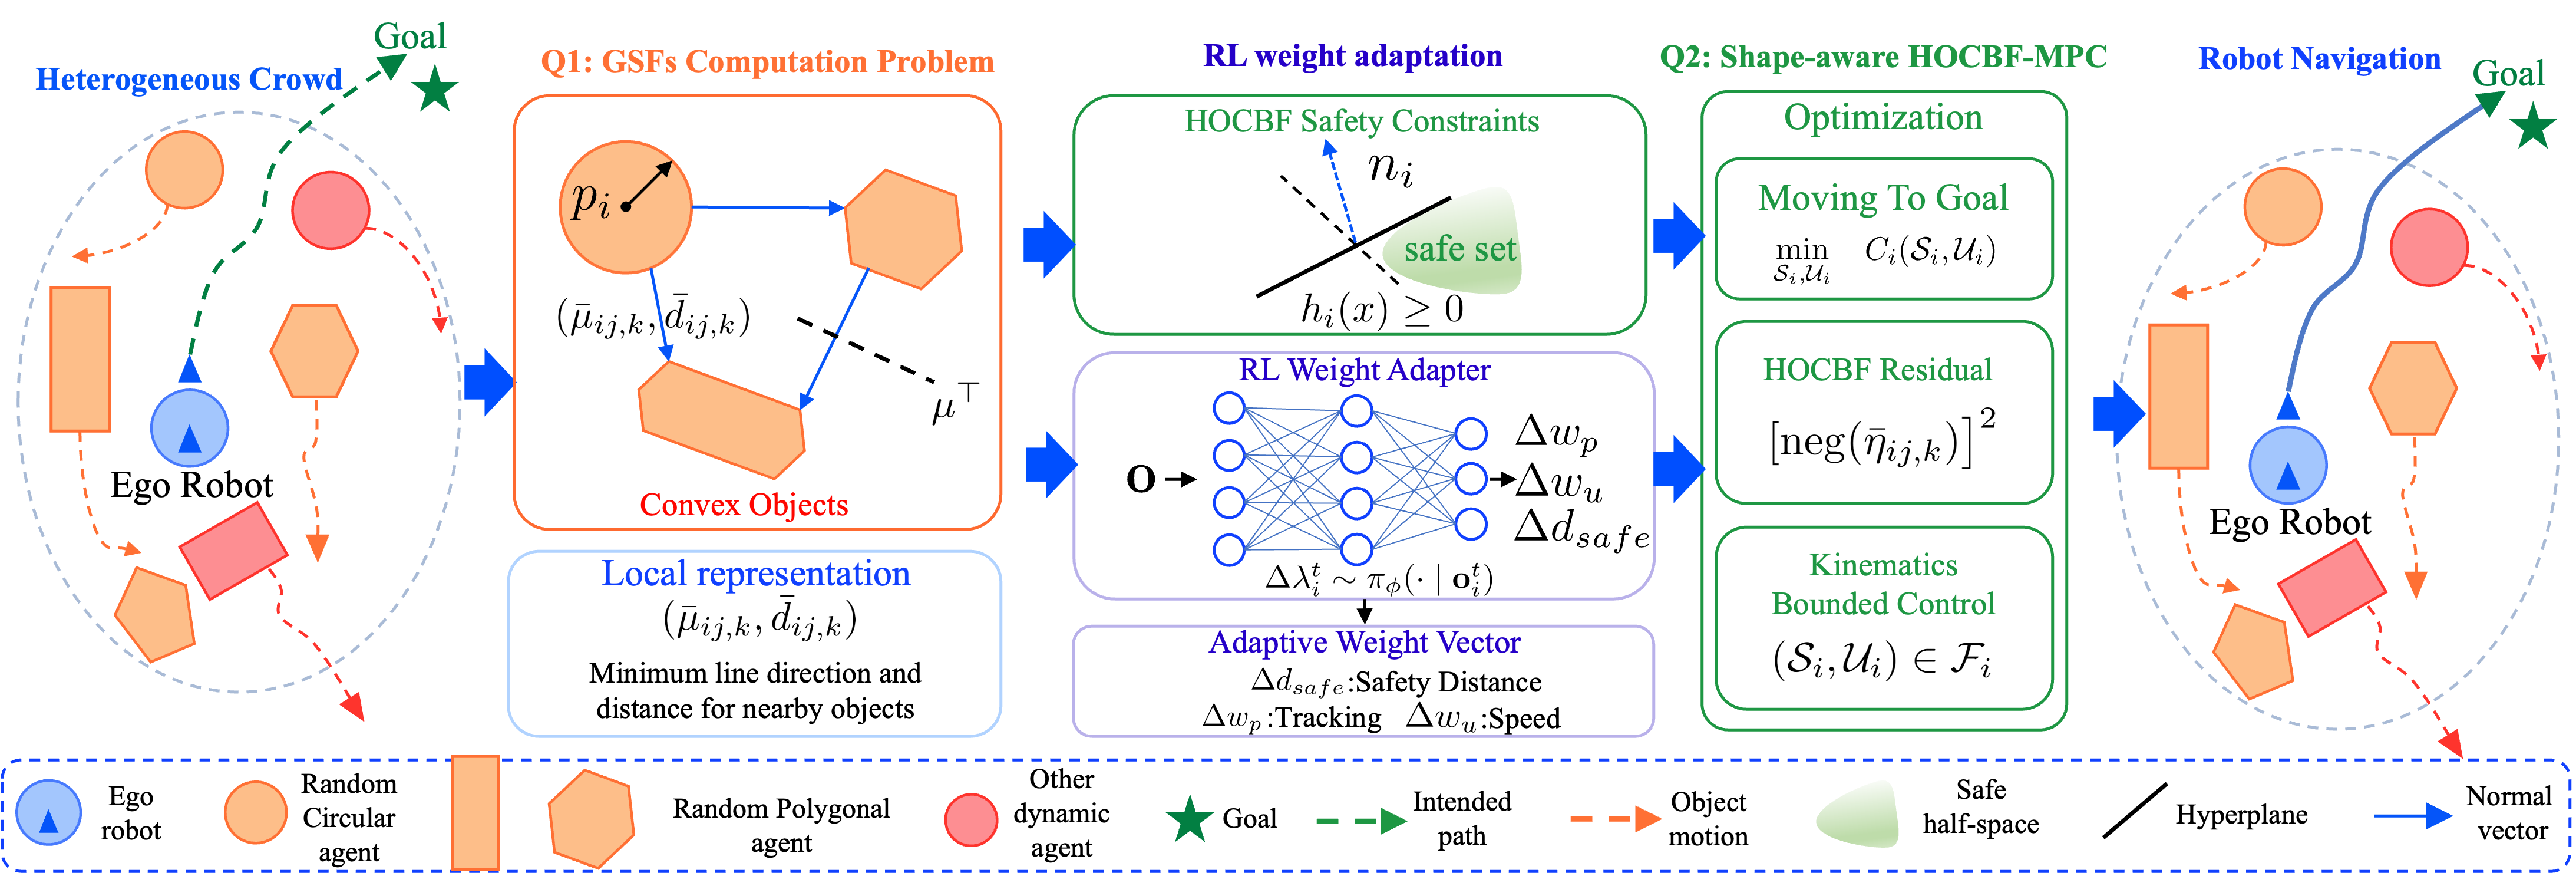


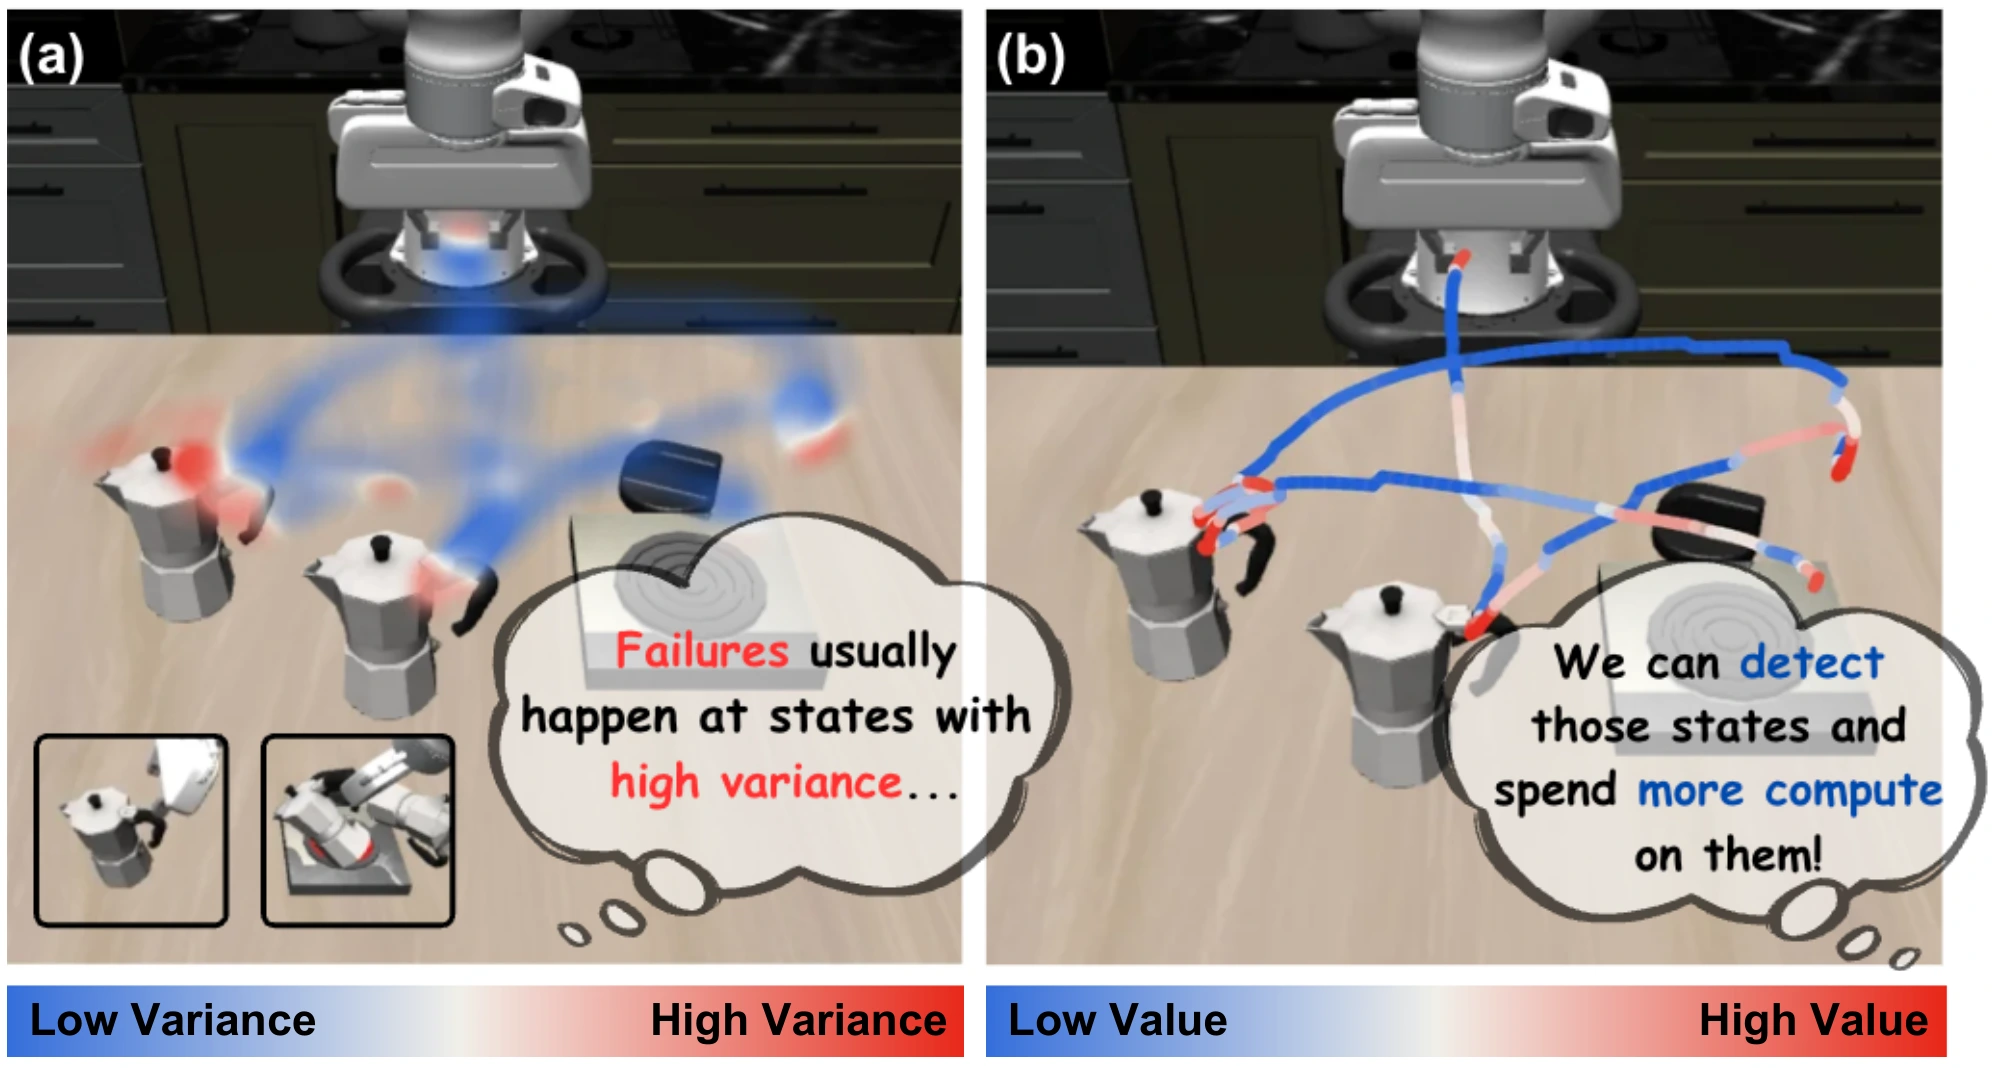
Efficient Inference & Test-Time Scaling 3 papers
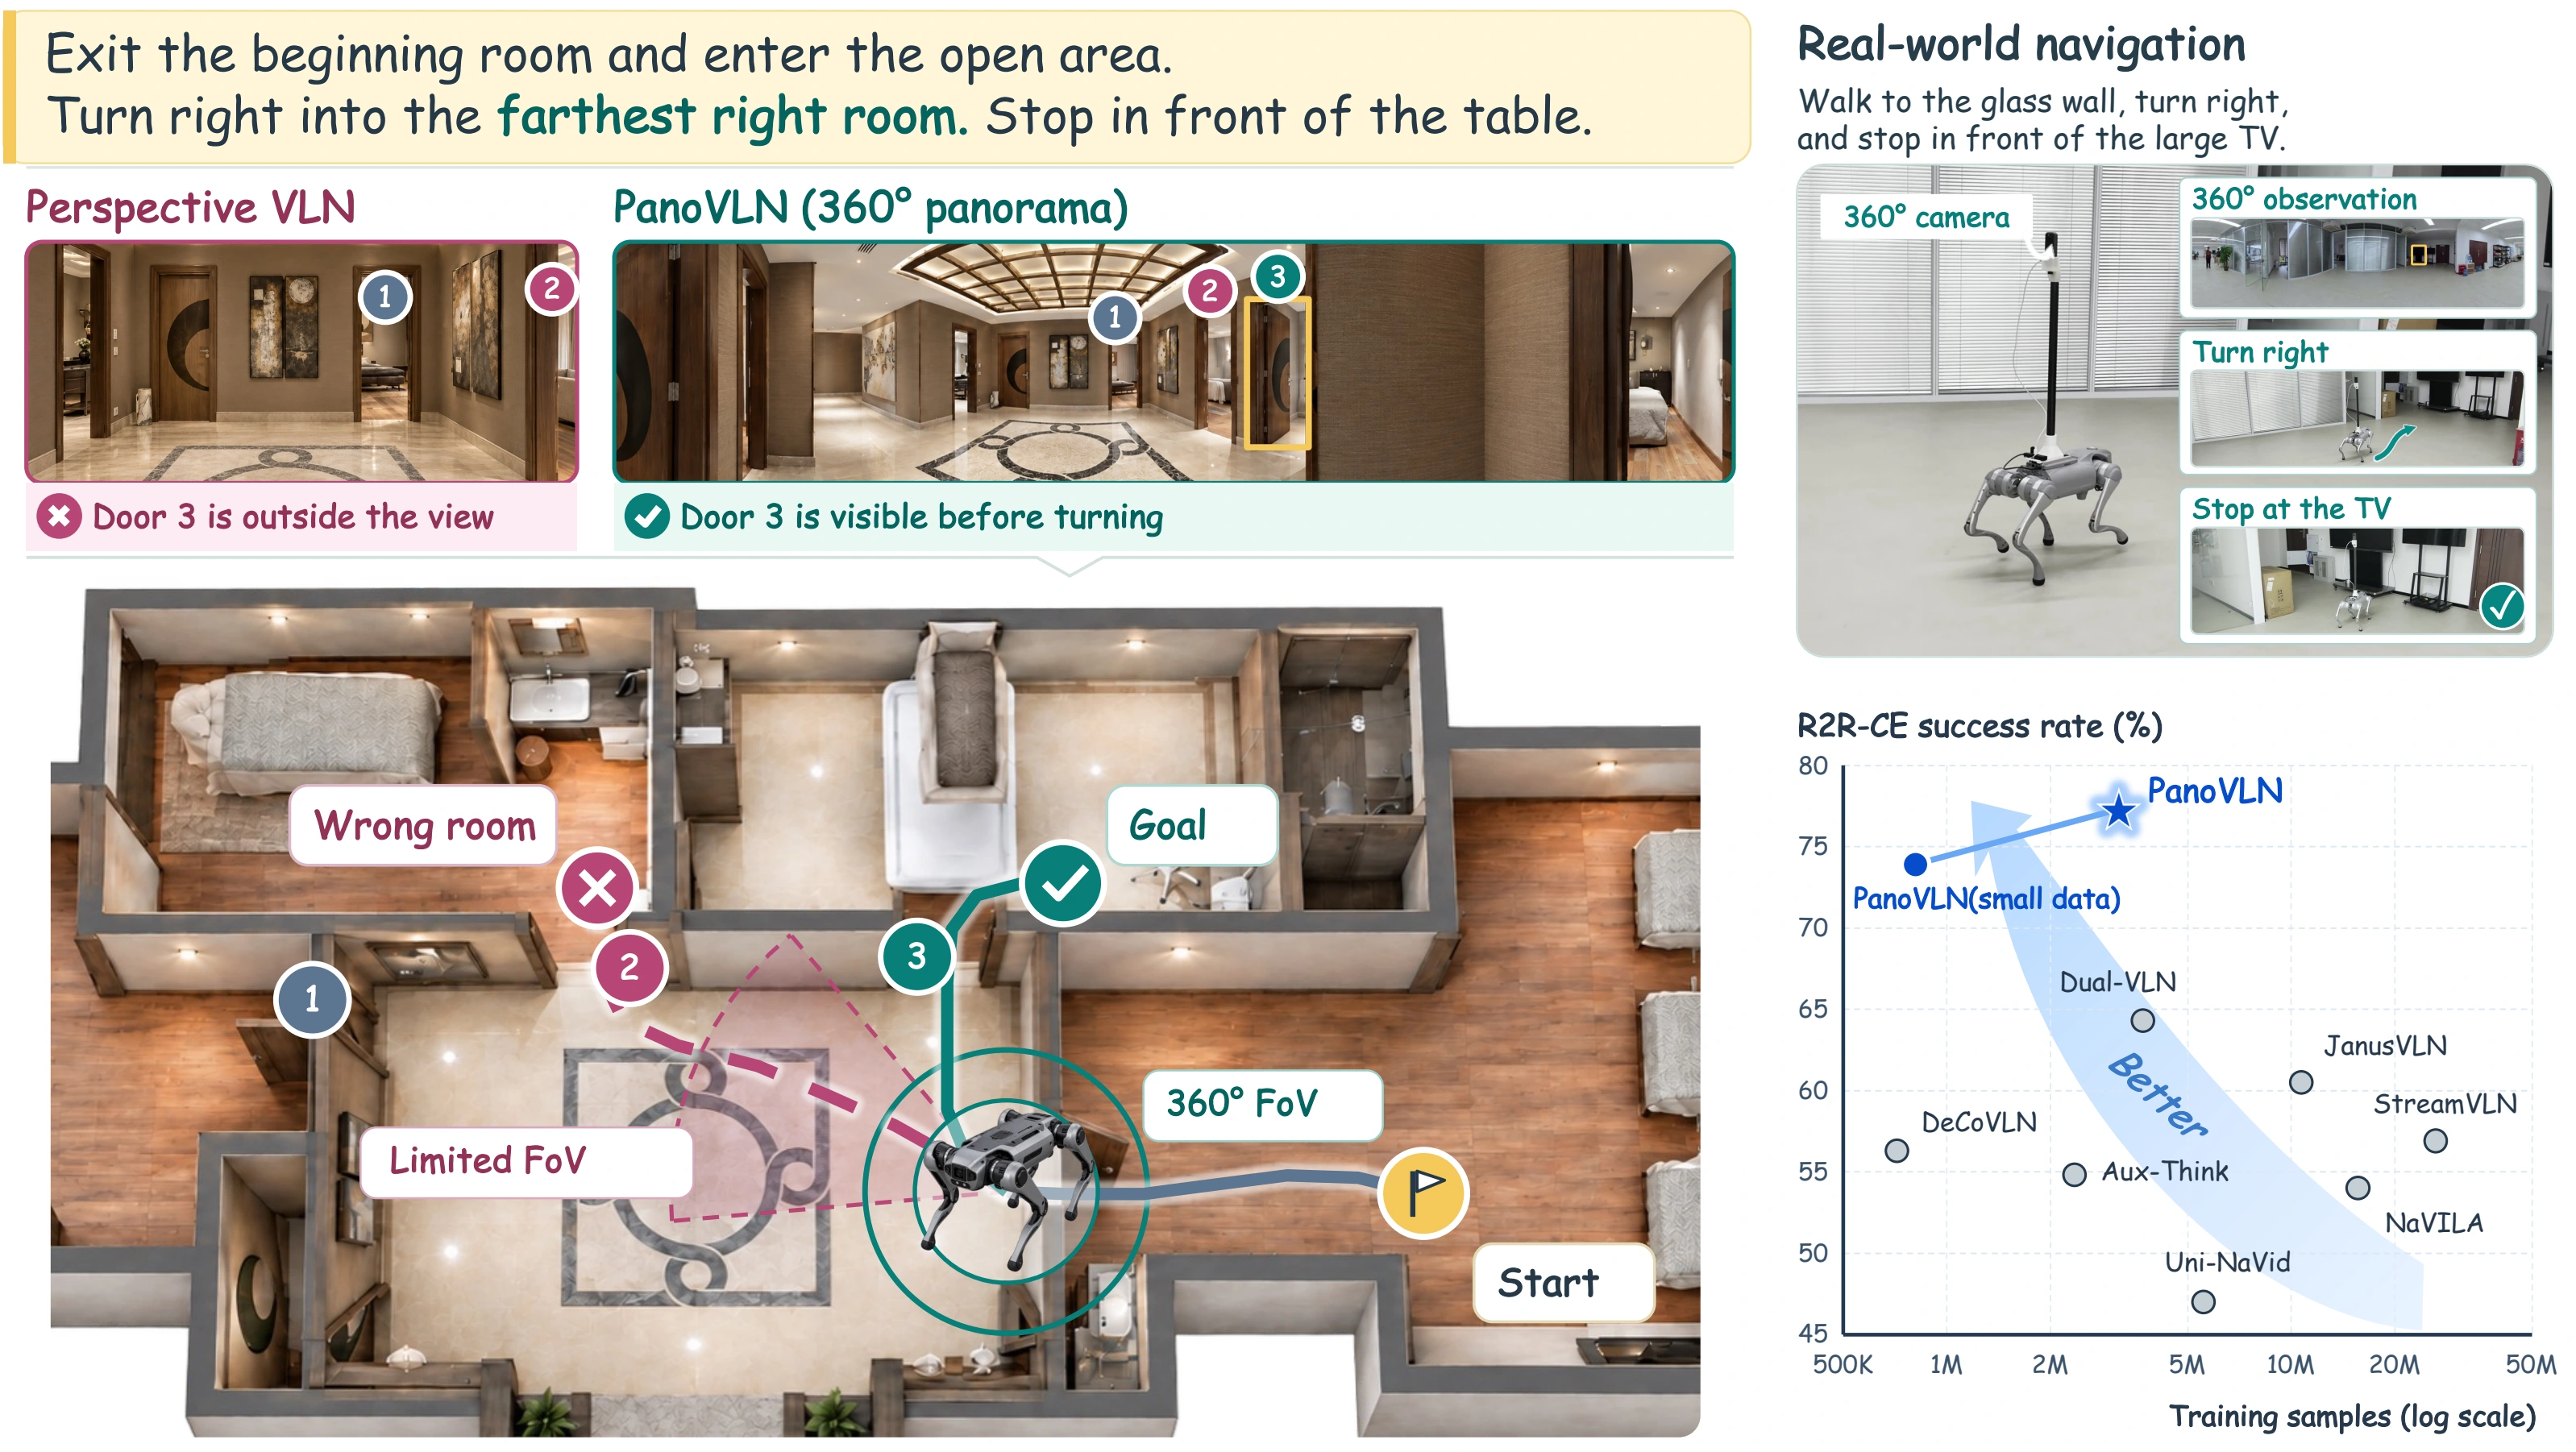
Real-time model execution through compact decoding, adaptive computation, and test-time verification.

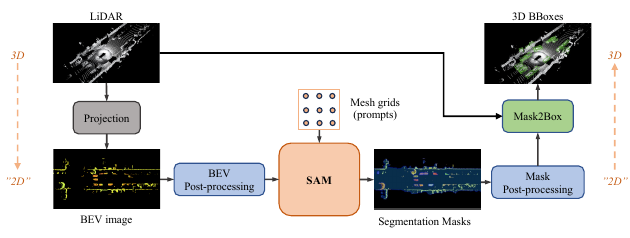
3D/4D & Multimodal Representation Learning 19 papers
Learning spatial, spatiotemporal, and cross-modal representations for scene understanding and embodied intelligence.







Professional Service
- Conference Area Chair: ICLR 2027, ICLR 2026.
- Conference Reviewer: CVPR, ICCV, ECCV, ICLR, ICML, NeurIPS, AAAI, IJCAI, ICRA, ICASSP, ACM Multimedia Asia.
- Journal Reviewer: TPAMI, TIP, TCSVT, TITS, RA-L, SCIS, TGRS.
- Invited Talks: Machine Intelligence, Midea Research Institute, 3D CVer, Shuzihuanyu, The Heart of Autonomous Driving, and Huawei Yinwang Intelligent Technology.
Industry Collaborations
I have previously collaborated with the following companies and research teams.
-
 Huawei Noah’s Ark Lab
华为诺亚
-
 Huawei Auto BU / Yinwang
华为车 BU(现为华为引望)
-
 Baidu
百度
-
 Changan Automobile
长安汽车
-
 Li Auto
理想汽车
-
 ByteDance Seed
字节 SEED
-
 ACE Robotics
大晓机器人
-
 Langyi Robotics
朗毅机器人
Contact
- Email: happinesslzcq@gmail.com
- CV: Download CV
- Google Scholar: Profile
- GitHub: happinesslz